From AI Ethics to Human Rights
, 14 min read
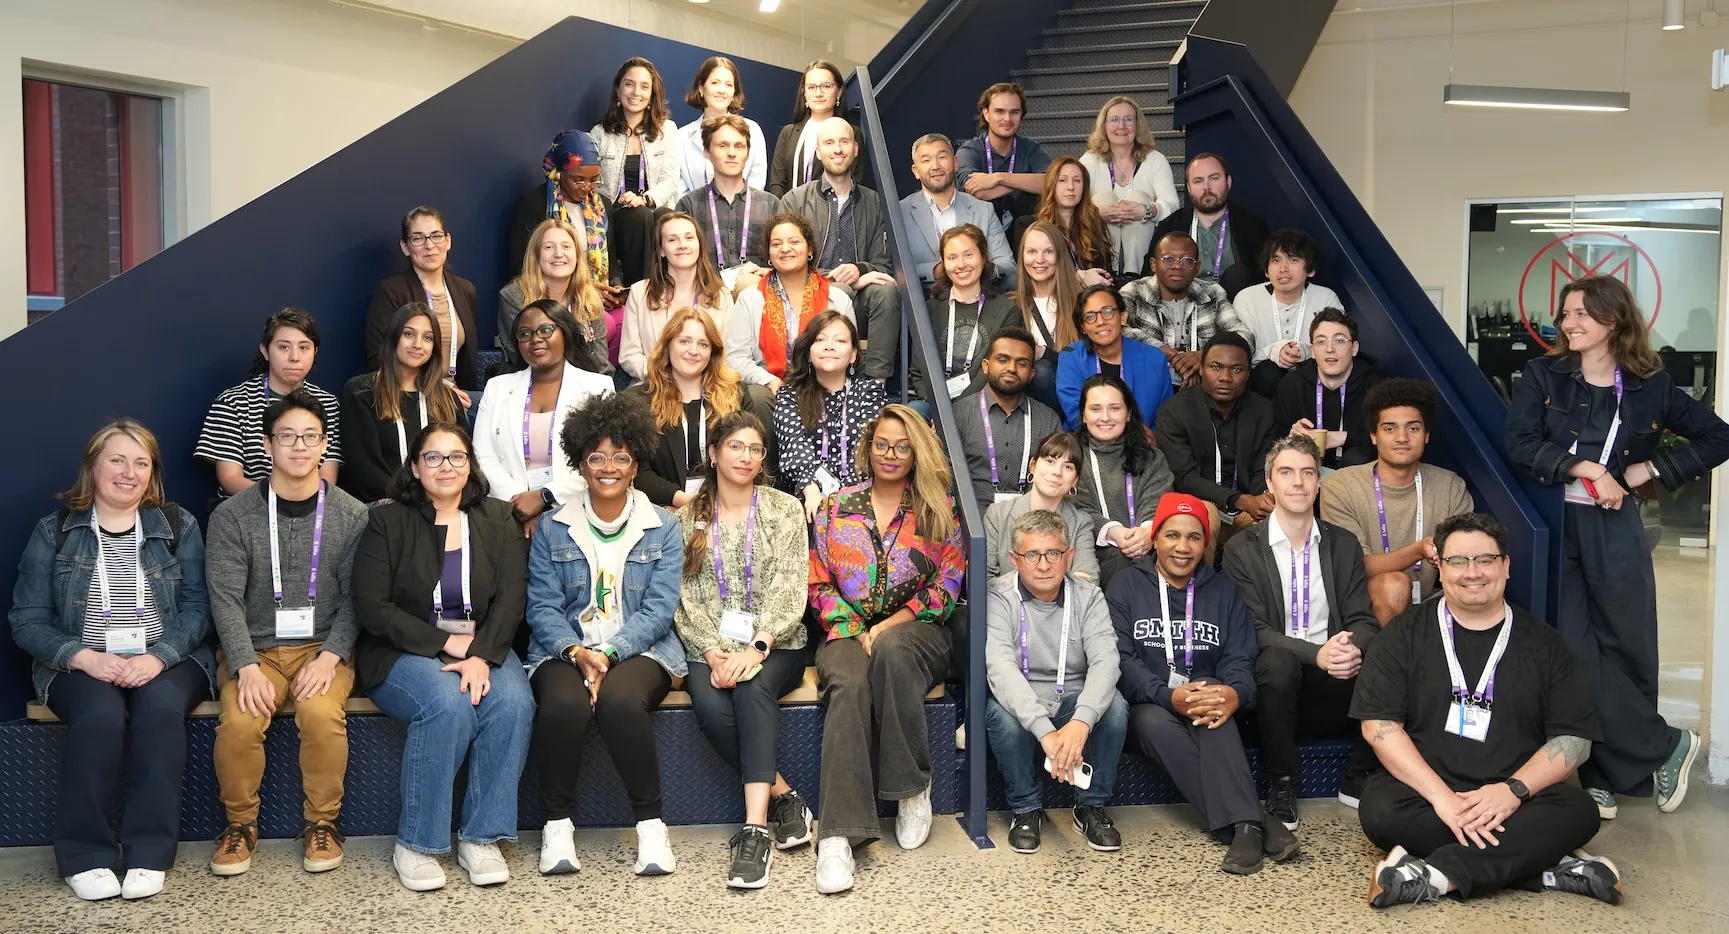
I went to the Mila Summer School on Responsible AI and Human Rights expecting fairness metrics, privacy-preserving ML, and maybe some techniques for reducing bias. My background is in software and cognitive science, so that’s what I assumed responsible AI meant. Most of the other participants were lawyers, policymakers, and social scientists, though, and we almost never talked about loss functions. We talked about international law, about AI as part of larger social systems, and about where the electricity, water, and minerals behind our compute come from.
It took me a few days to adjust. Most of the problems that came up during the week, like weak governance, exploitative mining supply chains, and systems that start discriminating once they’re deployed, don’t have technical fixes. They’re problems with institutions and with who holds power, and as an engineer I rarely deal with either one directly.
Ethics and human rights
Early on I noticed that the speakers mostly avoided the word “ethics.” In tech, “AI ethics” often means a company publishes a list of principles and sets up a review board. People call this ethics washing. The principles are vague and voluntary, so nobody is bound by them, and when they get in the way of a product launch, the launch usually wins.
The organizers framed the week around human rights instead. Catherine Régis described ethics as a set of competing principles with no clear floor. Human rights do have a floor: a set of standards that most of the world recognizes and that has been built into international law over decades, from the Universal Declaration of Human Rights to the UN Guiding Principles on Business and Human Rights. Under the Guiding Principles, states have a duty to protect rights, companies have a responsibility to respect them, and people whose rights are violated should have access to a remedy.
Some regulation already works this way. The EU AI Act came into force in August 2024 and was the first comprehensive AI law anywhere. Public bodies and certain other deployers of high-risk AI systems have to do a fundamental rights impact assessment before they start using them. The Act bans social scoring and manipulative techniques outright, and it bans police from using real-time facial recognition in public spaces except in a few narrow cases. Fines for the worst violations go up to €35 million or 7% of a company’s global annual turnover.
As an engineer, I found this framing easier to work with. It turns a philosophical debate into something like gathering requirements. Which rights does this system affect? Non-discrimination? Privacy? The right to a healthy environment? You can go and investigate each of those.
AI as a socio-technical system
Virginia Dignum’s talk on responsible AI changed where I draw the boundary around “the system.” I usually think of an AI system as the model: data goes in, predictions come out, and you measure performance on a benchmark. Dignum’s point was that the model is only one part. It sits inside institutions and economic incentives, and those shape what it ends up doing in the world.
Her example was a park bench. A bench is just a bench until someone adds armrests in the middle so homeless people can’t lie down on it, and then the design is a political choice. The data we collect, the objective we optimize, and the people we deploy a model on are choices in the same way, and each of them has effects we didn’t plan for.
Some of those effects are physical. Alex Hernandez-Garcia gave a talk on the environmental cost of AI. A primer from researchers at Hugging Face estimates that a ChatGPT query uses several times the energy of a Google search. Training GPT-4 reportedly took over 50 gigawatt-hours of electricity, about what San Francisco uses in three days. Li et al. (2023) estimated that training GPT-3 in Microsoft’s U.S. data centers used around 700,000 liters of fresh water for cooling. A more recent estimate from VU Amsterdam puts AI’s total water footprint in 2025 somewhere between 312 and 765 billion liters, which is in the same range as all the bottled water the world drinks in a year. Then there are the cobalt, lithium, and tungsten in our hardware, which are often mined under terrible conditions in the Global South, as Kate Crawford describes in Atlas of AI.
I never think about any of this when I’m watching a loss curve go down.
Examples of harm
If you’re writing Python at a desk, the environmental costs can feel far away. The cases where specific people were harmed are harder to ignore.
In 2016, ProPublica looked at COMPAS, a tool used in U.S. courts to predict whether a defendant will reoffend. Among defendants who didn’t go on to reoffend, Black defendants were almost twice as likely as white defendants to have been labeled high risk. White defendants who did reoffend were more often labeled low risk. Race wasn’t one of COMPAS’s inputs, but the features it did use were correlated with race, so the model picked up the biases in the criminal justice data it learned from. A later study from Dartmouth found that people recruited online, with no legal background, predicted reoffending about as accurately as COMPAS.
In 2020, the UK Court of Appeal ruled that South Wales Police’s use of automated facial recognition was unlawful. It breached the right to privacy under Article 8 of the European Convention on Human Rights, and the police hadn’t met their duties under data protection and equality law. They had never checked whether the software was biased by race or sex. Two years before that, Buolamwini and Gebru’s Gender Shades study had found that commercial gender classifiers had error rates as low as 0.8% for lighter-skinned men and as high as 34.7% for darker-skinned women.
Hiring has the same problem. Amazon trained a resume screener on ten years of its own hiring data. Most of the engineers it had hired were men, so the model learned to downgrade resumes that included the word “women’s,” as in “women’s chess club captain,” and to favor wording that men tended to use. Amazon eventually dropped the project. In 2023, the EEOC settled its first AI hiring discrimination case, against a company whose software automatically rejected women over 55 and men over 60.
Human rights assessments
So how would you catch problems like these before a system is deployed? Samone Nigam from BSR ran a workshop on Human Rights Assessments (HRAs), which are one way to do it.
An HRA is a process for identifying and evaluating how a project could affect people’s human rights. It’s close enough to an engineering process that it made sense to me right away. Take the resume screener. A typical ML evaluation asks whether the model picks candidates who go on to do well. An HRA asks different questions. Whose resumes was the model trained on? Does it penalize gaps in employment, which women and caregivers are more likely to have? Does it prefer wording that one group uses more than others?
Then you rank the risks by how severe they are for the people affected: how many people could be harmed, how badly, and whether the harm can be undone. You end up with a list of the rights your system might violate and how seriously, which gives you a lot more to act on than “be ethical.”
Some governments already require assessments like this. Besides the EU AI Act, the Netherlands has a Fundamental Rights and Algorithms Impact Assessment for public institutions, and Canada’s federal government uses a tiered Algorithmic Impact Assessment tool for its own automated systems.
Implicated subjects
When you work on the engineering and research side, it’s easy to feel like policy and law happen somewhere far above the daily work of building models.
Alex Hernandez-Garcia talked about the “implicated subject,” an idea from the scholar Michael Rothberg, who developed it to describe people’s relationship to historical injustices. An implicated subject is neither a perpetrator nor a victim, but someone who helps keep a harmful system going, or benefits from it, without directly causing the harm. That describes a lot of people in tech. Our work helps build and maintain systems that have these effects, even when we mean well.
Nobody has to be a villain for this to apply. I can have good intentions and still be responsible for what my work contributes to.
It applies to cognitive science in a specific way, because we use AI models as models of the mind. Henrich and colleagues pointed out that most behavioral research data comes from WEIRD (Western, Educated, Industrialized, Rich, and Democratic) populations, and models trained on that data can lead to theories of cognition that don’t hold for most people. If you use an LLM trained on internet text as a model of human language processing, its biases come along with it and can skew your conclusions without you noticing.
For me, this mostly means changing how I plan projects. I want to look harder at the assumptions behind my data and research questions, and count the environmental cost of compute as part of the cost of the research. And sometimes, as Su Lin Blodgett said in a talk on ethical reasoning, the right decision is not to build the thing at all.
Cognitive science and AI safety
Most of the week was about governance, which makes sense. But I kept wondering what cognitive science could add that lawyers and policymakers can’t, and I think part of the answer is what we know about why brains are so robust.
People in NeuroAI are already working on this. In a roadmap paper called “NeuroAI for AI Safety,” Mineault et al. (2025) ask what AI safety research can learn from the brain, since it’s the only general intelligence we know of that works reasonably well. People generalize to new situations in ways current models can’t, and models make mistakes no person would make. One explanation is that evolution, working through a “genomic bottleneck,” gave us strong inductive biases that constrain learning in useful ways. If we could reverse-engineer those constraints, instead of only imitating human behavior, we might get systems that fail less badly. The paper’s proposals include building digital twins of sensory systems to make models harder to fool with adversarial attacks, and trying to infer the loss functions the brain actually uses. Those seem to be homeostatic and to balance many objectives at once, which makes them much richer than the reward models we use now.
A Google DeepMind paper on AGI safety (Shah et al., 2025) reminded me of the HRA workshop, because it’s also a risk assessment. It sorts risks into four areas and focuses on two of them: misuse, where a person uses the AI to cause harm, and misalignment, where the AI pursues goals its developers didn’t intend. Against misalignment it proposes two lines of defense. The first is training the model to be aligned, with help from amplified oversight, which means using AI to help humans supervise AI systems that are more capable than they are. How you reliably evaluate something smarter than you is an interesting cognitive science question in its own right. The second is security at the level of the whole system, like monitoring and access controls, so the AI can still be contained if alignment fails. I like that they plan for the case where alignment doesn’t work.
Explainability is the other area I think about. Rahimi et al. (2025) found that attribution scores from XAI methods, which estimate how much each input word contributed to a language model’s output, can help predict brain activity during language processing. It’s an exciting result, but I’m cautious about this kind of work. NIST’s principles for explainable AI (Phillips et al., 2021) say an explanation has to be accurate, not just understandable. When model attributions line up nicely with neural data, it’s tempting to conclude you’ve found a real cognitive mechanism, when you might be explaining a quirk of the model you built. An explanation can be easy to interpret and still be wrong.
Cognitive offloading and neural data
There’s also a cost that rarely comes up in policy discussions, which is cognitive offloading. As AI tools become part of research workflows, we hand them more of the hard thinking. Jolie Dobre argues in UX Matters that relying on AI for difficult tasks can erode the critical thinking you need to build expertise (Dobre, 2025). The more of that work you hand off, the harder it gets to tell whether the AI’s output is any good. There’s some early evidence for this. In a small EEG study, Kosmyna et al. (2025) found that people who wrote essays with ChatGPT showed weaker brain connectivity, and remembered less of what they had written, than people who wrote without it.
AI is also getting better at decoding neural data. Ienca and Andorno (2017) argued that existing privacy protections won’t be enough and proposed new rights, including a right to cognitive liberty (control over your own mental processes) and a right to mental privacy. Until recently, your thoughts were private because nobody had a way to read them. My field uses AI to model the brain all the time, and it could end up being the field that changes that.
Takeaways
I went expecting a technical program and spent most of the week on governance, international law, and human dignity. I came away thinking of ethical principles as what you aim for, and human rights as a minimum that comes with ways to hold people accountable when they fall below it.
For people like me who build these systems, that means practical work: looking hard at training data, doing impact assessments that are more than box-ticking, and using what we know about the brain to build systems that fail gracefully. It also means being honest that leaning on AI tools might be weakening the judgment we need for all of this. I’m back to writing code now, and I find the human rights framing more useful than the usual “be ethical” advice.
References
Buolamwini, J., & Gebru, T. (2018). Gender Shades: Intersectional accuracy disparities in commercial gender classification. Proceedings of the 1st Conference on Fairness, Accountability and Transparency, PMLR 81, 77-91.
Cross, J. L., Choma, M. A., & Onofrey, J. A. (2024). Bias in medical AI: Implications for clinical decision-making. PLOS Digital Health, 3(11), e0000651.
Dobre, J. (2025, February 3). Designing AI for Human Expertise: Preventing Cognitive Shortcuts. UX Matters.
Henrich, J., Heine, S. J., & Norenzayan, A. (2010). The weirdest people in the world? Behavioral and Brain Sciences, 33(2-3), 61-83.
Ienca, M., & Andorno, R. (2017). Towards new human rights in the age of neuroscience and neurotechnology. Life Sciences, Society and Policy, 13(1), 5.
Kosmyna, N., et al. (2025). Your Brain on ChatGPT: Accumulation of Cognitive Debt when Using an AI Assistant for Essay Writing Task. arXiv preprint arXiv:2506.08872.
Li, P., et al. (2023). Making AI Less “Thirsty”: Uncovering and Addressing the Secret Water Footprint of AI Models. arXiv preprint arXiv:2304.03271.
Mineault, P., et al. (2025). NeuroAI for AI Safety. arXiv preprint arXiv:2411.18526.
Phillips, P. J., et al. (2021). Four Principles of Explainable Artificial Intelligence. NIST Internal Report 8312. National Institute of Standards and Technology.
Rahimi, M., Yaghoobzadeh, Y., & Daliri, M. R. (2025). Explanations of Deep Language Models Explain Language Representations in the Brain. arXiv preprint arXiv:2502.14671.
Shah, R., et al. (2025). An Approach to Technical AGI Safety and Security. arXiv preprint arXiv:2504.01849.